The Story of How Machines Learned to Learn
The Story of How Machines Learned to Learn
Imagine this.
It is 1950.
There is no ChatGPT.
No smartphone.
No Google.
No cloud.
No giant AI model sitting in a data center.
There is just a scientist looking at a machine and asking a question that would change technology forever:
"Can machines think?"
And with that question, our story begins.
ERA 01 — CAN MACHINES THINK?
1950–1956 · The Birth of the AI Idea
This was not yet the age of intelligent machines.
It was the age of a crazy question.
Alan Turing — 1950
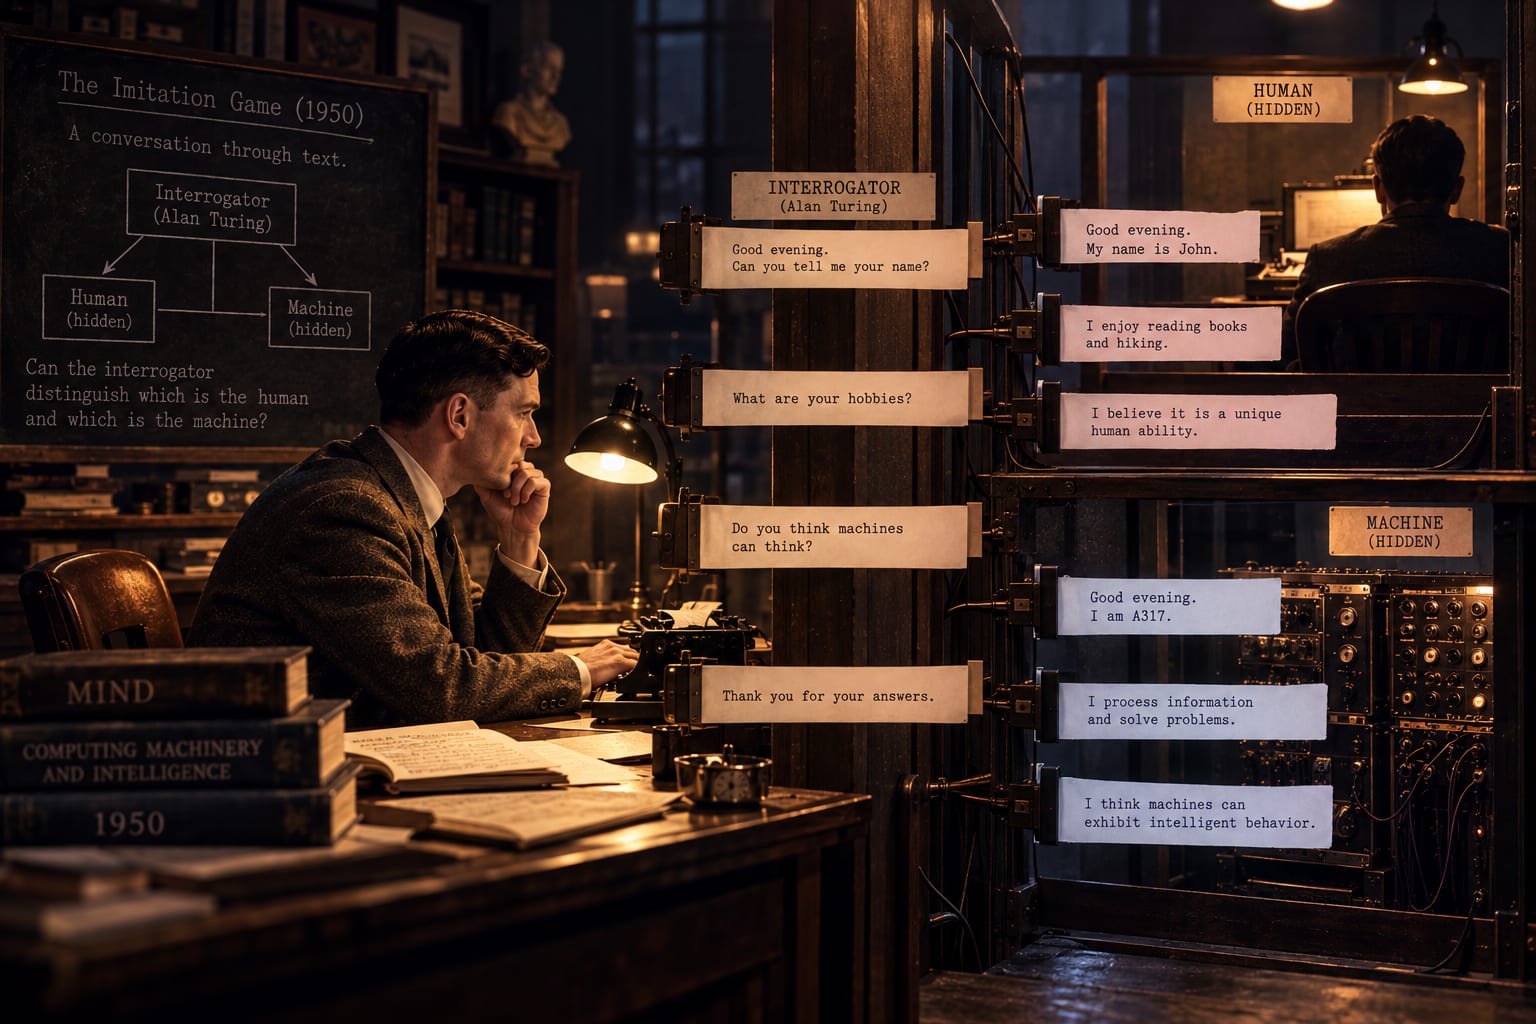
Alan Turing published a paper called Computing Machinery and Intelligence.
Instead of getting trapped in the question of what exactly "thinking" means, Turing proposed a practical experiment called the Imitation Game.
The basic idea:
A human communicates through text with another participant without seeing who is on the other side.
Could a machine respond in a way that makes the human unable to reliably distinguish it from a person?
This later became known as the Turing Test.
But Turing wasn't building today's AI.
He was doing something even more important.
He was asking:
"Could intelligence be something a machine can reproduce?"
And a few years later, another researcher would give this dream a name.
John McCarthy — 1955
McCarthy, along with Marvin Minsky, Nathaniel Rochester and Claude Shannon, proposed a summer research project at Dartmouth.
The proposal made an extraordinary assumption:
If every aspect of learning and intelligence could be described precisely enough, perhaps machines could simulate it.
And the proposal used a new phrase:
Artificial Intelligence
The proposal was written in 1955.
The Dartmouth workshop itself took place in 1956.
That workshop is widely regarded as a foundational event in the formation of AI as a research field.
And now the first era ends.
The question was no longer only:
"Can machines think?"
The researchers now had a new problem:
"How do we actually make a machine behave intelligently?"
That led to the next era.
ERA 02 — TEACH THE MACHINE THE RULES
1950s–1980s · Symbolic AI and Expert Systems
Imagine teaching a computer how to identify a cat.
You might write:
IF ears are pointed
AND body has fur
AND animal has four legs
AND tail is visible
THEN probably CAT
Now imagine doing this for everything.
Cats.
Dogs.
Diseases.
Chess positions.
Languages.
Industrial processes.
The thinking was:
Maybe intelligence is just a giant collection of rules.
This became the world of symbolic AI, where knowledge could be represented explicitly using symbols, logic and rules.
One important development was the rise of expert systems.
The idea was simple:
Human expert
knows the rules.
Programmer
puts those rules into the computer.
Computer
uses those rules to reach conclusions.
Systems such as MYCIN demonstrated how computers could apply large collections of rules in specialized medical domains.
For a while, this looked incredibly promising.
But then reality appeared.
Imagine your system has:
10,000 rules.
What happens when case 10,001 arrives?
You add another rule.
Then another exception.
Then another rule to handle the exception.
And eventually the machine faces something it has never seen before.
A human might say:
"That's unusual, but I understand the pattern."
The rule system says:
"There is no rule for that."
And this exposed the fundamental weakness of rule-based AI:
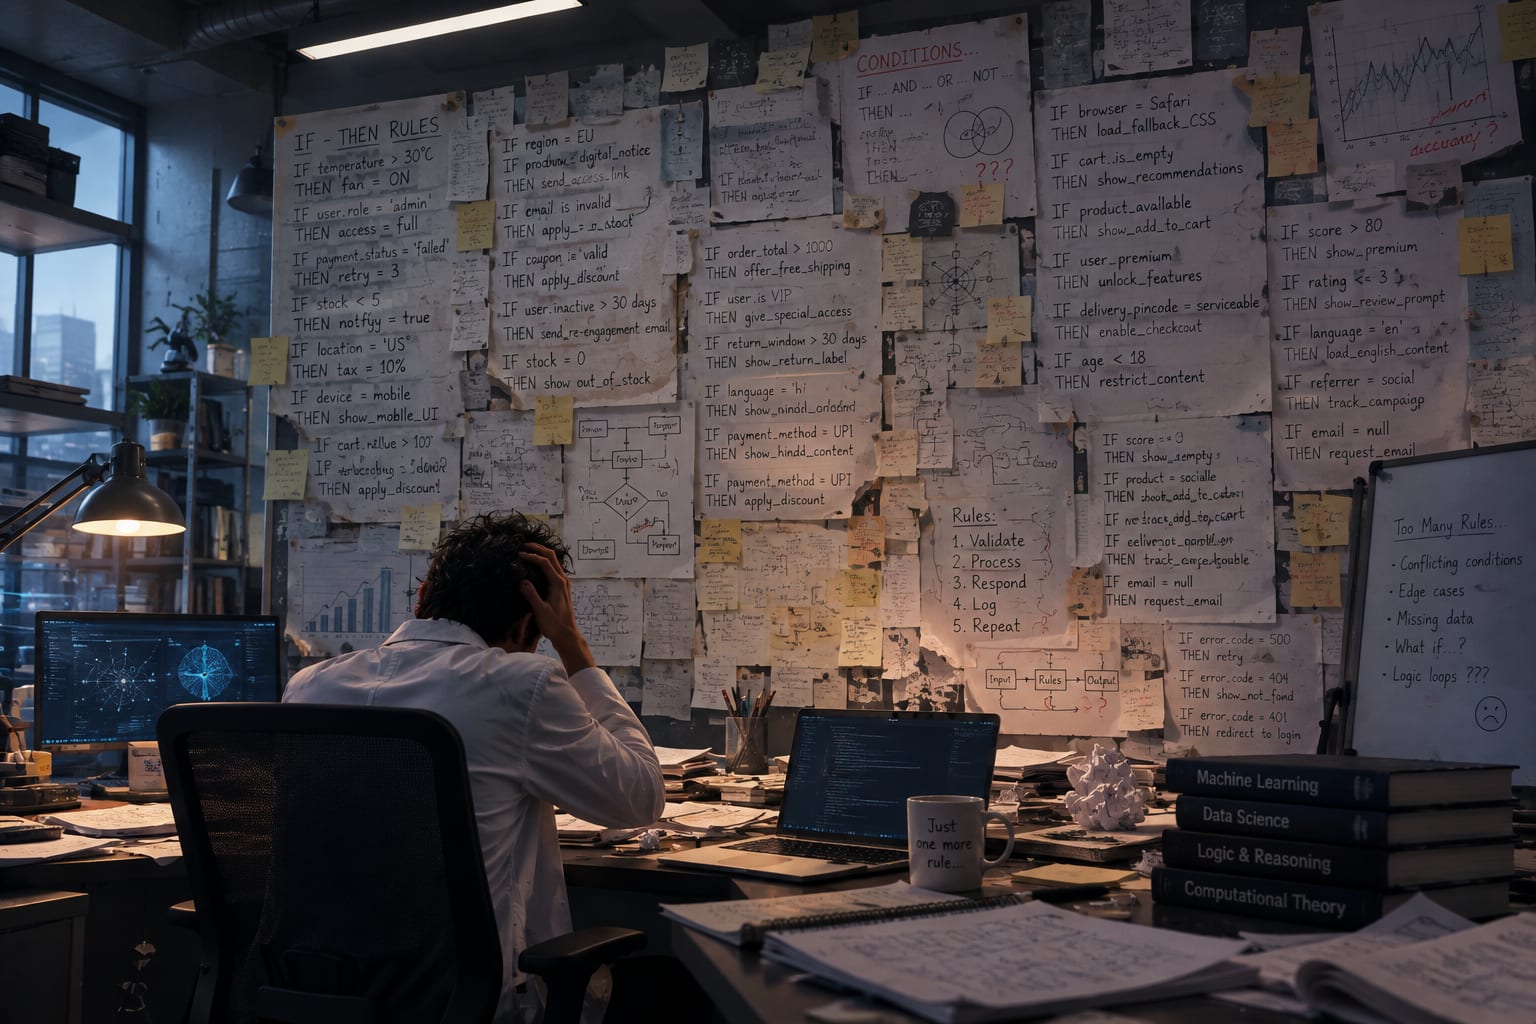
The world has too many possibilities to write down manually.
But there was another problem.
The machines themselves were still weak.
And the expectations surrounding AI were becoming very large.
ERA 03 — THE AI WINTER
1970s–1980s · When the Hype Collapsed
The promises had become enormous.
Researchers expected AI to achieve much more than the technology of the time could realistically deliver.
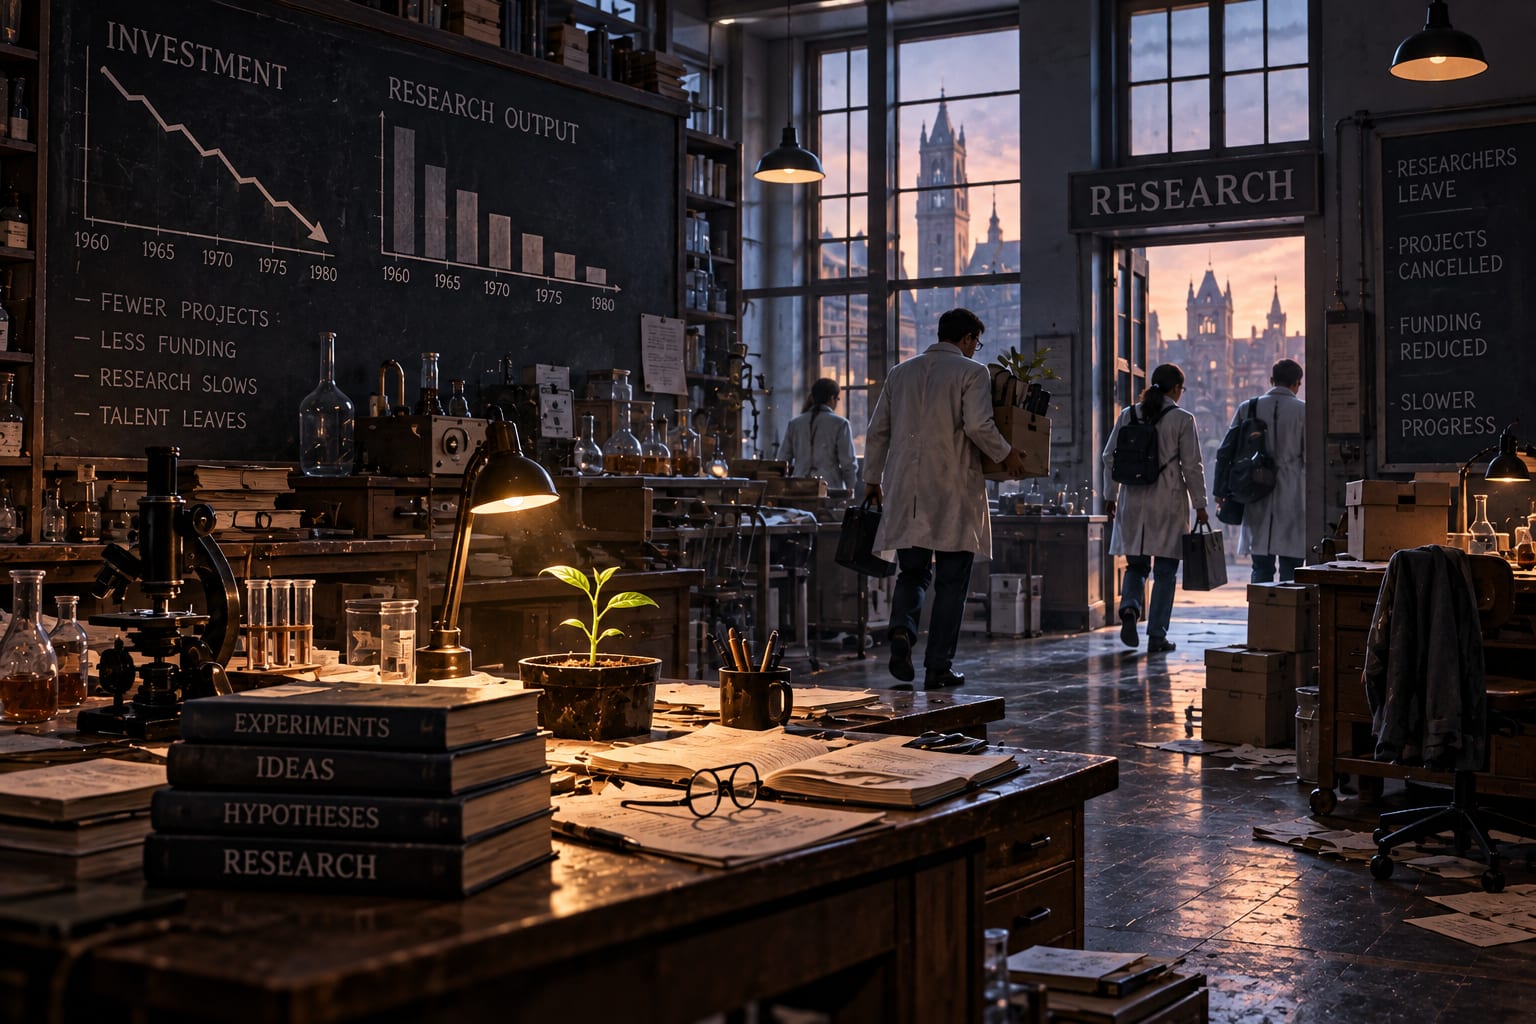
But computers had limited processing power.
Data was limited.
Many difficult problems were still unsolved.
And systems that worked beautifully in narrow demonstrations often struggled outside their controlled environments.
Then came disappointment.
Funding declined.
Research slowed.
Confidence disappeared.
These periods became known as AI winters.
The history is not one single winter. There were multiple periods of reduced enthusiasm and investment, notably during the 1970s and again in the late 1980s/early 1990s.
Imagine AI as a plant.
The world expected a giant tree.
But the plant was still small.
So instead of growing faster...
the money stopped coming.
The excitement became quieter.
But the story was not over.
Far from it.
Because researchers began changing the question again.
Instead of saying:
"Tell the machine every rule."
They began asking:
"What if the machine learns the rules from examples?"
And now we enter a completely different era.
ERA 04 — DON'T PROGRAM EVERY ANSWER
1950s–2000s · Machine Learning
Here is the new idea.
Suppose I show a computer thousands of images.
I tell it:
Cat.
Cat.
Dog.
Dog.
Instead of manually programming every visual rule, we give the system examples and an algorithm that can learn statistical patterns from those examples.
Now the pipeline looks more like:
DATA
  ↓
LEARNING ALGORITHM
  ↓
LEARNED MODEL
  ↓
PREDICTION
This is the basic idea behind machine learning.
And machine learning did not suddenly appear in the 1990s.
Its history goes back much further. Arthur Samuel was already using the term machine learning in 1959 while describing a checkers program capable of improving from experience.
But over the 1990s and 2000s, statistical and data-driven methods became increasingly important.
Why?
Because three things were getting better:
more data
better algorithms
more computing power
But machine learning had a weakness.
Humans were still doing a lot of the thinking.
We often had to decide:
"Which features should the model look at?"
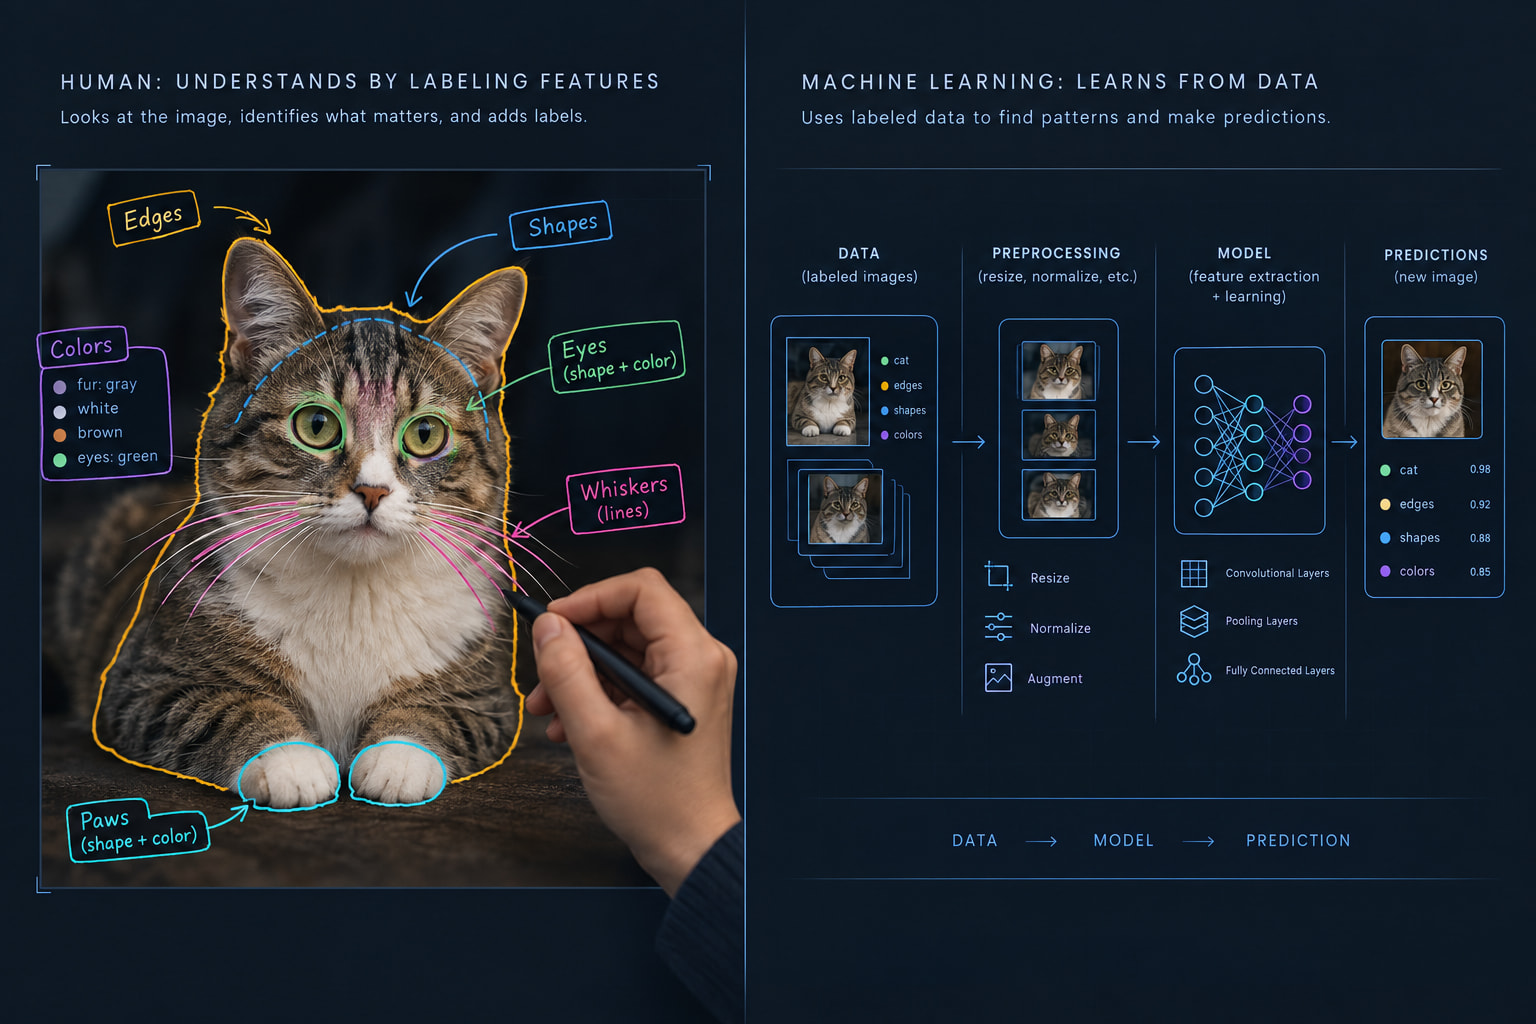
For our cat example, a human might manually engineer features such as:
edge patterns
shapes
textures
colors
object dimensions
The machine learned from data.
But humans often had to tell it what information to pay attention to.
And that brings us to another major shift.
ERA 05 — WHAT IF THE MACHINE LEARNS THE FEATURES TOO?
1980s–2010s · Deep Learning
Now imagine something more ambitious.
Instead of humans manually describing useful features...
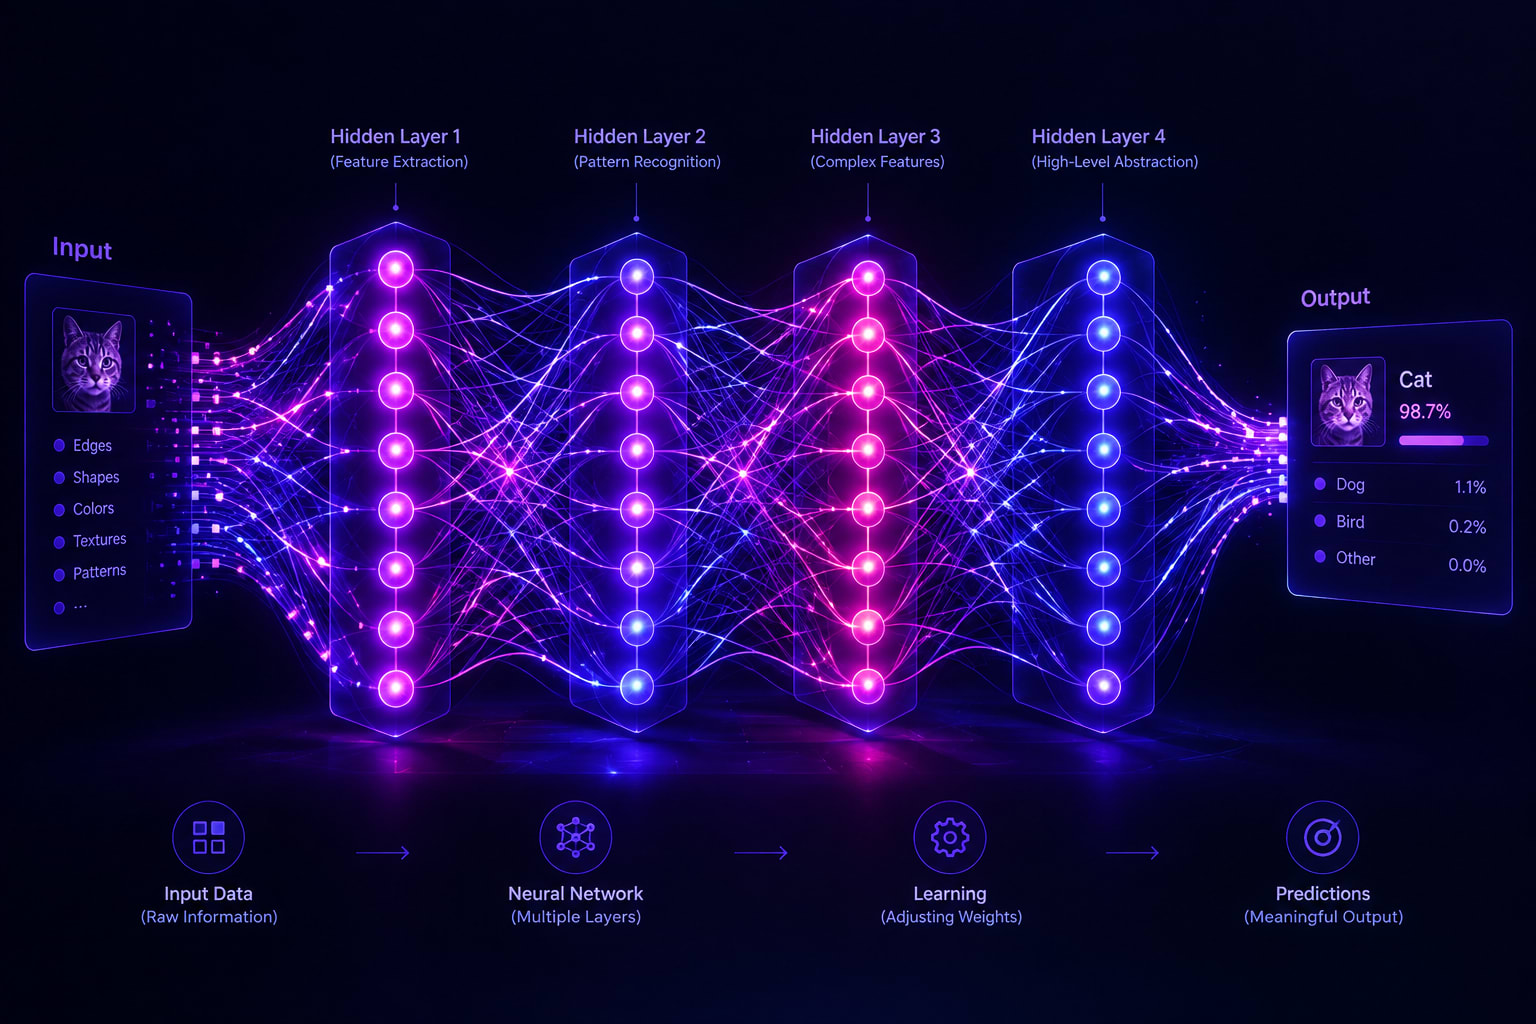
what if the neural network could learn useful internal representations by itself?
This is the basic idea behind deep learning.
Deep learning is a branch of machine learning built largely around multi-layer neural networks.
One important milestone came in 1986, when David Rumelhart, Geoffrey Hinton and Ronald Williams published influential work on backpropagation, showing how multi-layer networks could learn internal representations.
But the real explosion came later.
Why?
Because the world suddenly had ingredients neural networks desperately wanted:
More data
The internet was producing enormous amounts of digital information.
More computation
GPUs became extremely useful for neural-network workloads.
Better hardware
Models could be trained on much larger datasets.
So the recipe became:
BIG DATA
   +
POWERFUL COMPUTE
   +
NEURAL NETWORKS
   ↓
DEEP LEARNING
And then something spectacular happened.
Machines started getting much better at seeing.
ERA 06 — TEACHING MACHINES TO SEE
2012 · The Computer Vision Breakthrough
Imagine giving a machine millions of pictures.
Not ten.
Not a thousand.
Millions.
This was happening with ImageNet.
The 2012 ImageNet Large Scale Visual Recognition Challenge used roughly 1.2 million training images across 1,000 categories.
Then came:
AlexNet
Created by:
Alex Krizhevsky Ilya Sutskever Geoffrey Hinton
AlexNet was an eight-layer convolutional neural network and achieved a dramatic improvement on the ImageNet classification benchmark.
Its reported top-5 error was 15.3%, compared with 26.2% for the next-best entry under the comparison reported in the paper.
The important part was not simply that one competition was won.
The bigger message was:
Deep neural networks could learn powerful visual representations from huge datasets.
And this helped accelerate modern computer vision.
Soon, similar technology would contribute to applications such as:
face recognition
object detection
image search
medical imaging
product recognition
and much more.
Machines were becoming much better at seeing.
But there was another thing humans needed machines to deal with.
Something even more complicated than pixels.
Language.
ERA 07 — TEACHING MACHINES TO UNDERSTAND LANGUAGE
2010s · NLP + Neural Networks
At first glance, language looks easy.
A sentence contains only a few words.
Surely that must be easier than processing millions of pixels?
Not really.
Consider this:
"The chicken is ready to eat."
Is the chicken hungry?
Or is the chicken about to be eaten?
Now:
"I saw a man with a telescope."
Who has the telescope?
The man?
Or me?
Human language is full of ambiguity.
Meaning depends on:
context
relationships between words
previous sentences
world knowledge
and sometimes even common sense.
Early neural NLP systems often used Recurrent Neural Networks, or RNNs.
An RNN processes a sequence step by step while maintaining a hidden state.
That works reasonably well for short sequences.
But as the sequence gets longer, remembering earlier information becomes difficult.
Then came:
LSTM — 1997
Sepp Hochreiter and Jurgen Schmidhuber introduced Long Short-Term Memory, designed specifically to help recurrent networks preserve information across much longer time intervals.
LSTMs were an important improvement.
But they still relied on recurrent processing.
And researchers were about to make a much bigger change.
Instead of asking:
"How do we make the machine remember more?"
They asked:
"What if every important word could directly look at every other important word?"
That question leads directly to the Transformer.
ERA 08 — ATTENTION CHANGES THE GAME
2017 · The Transformer Era
It is 2017.
Eight researchers publish a paper called:
Attention Is All You Need
And AI history takes another sharp turn.
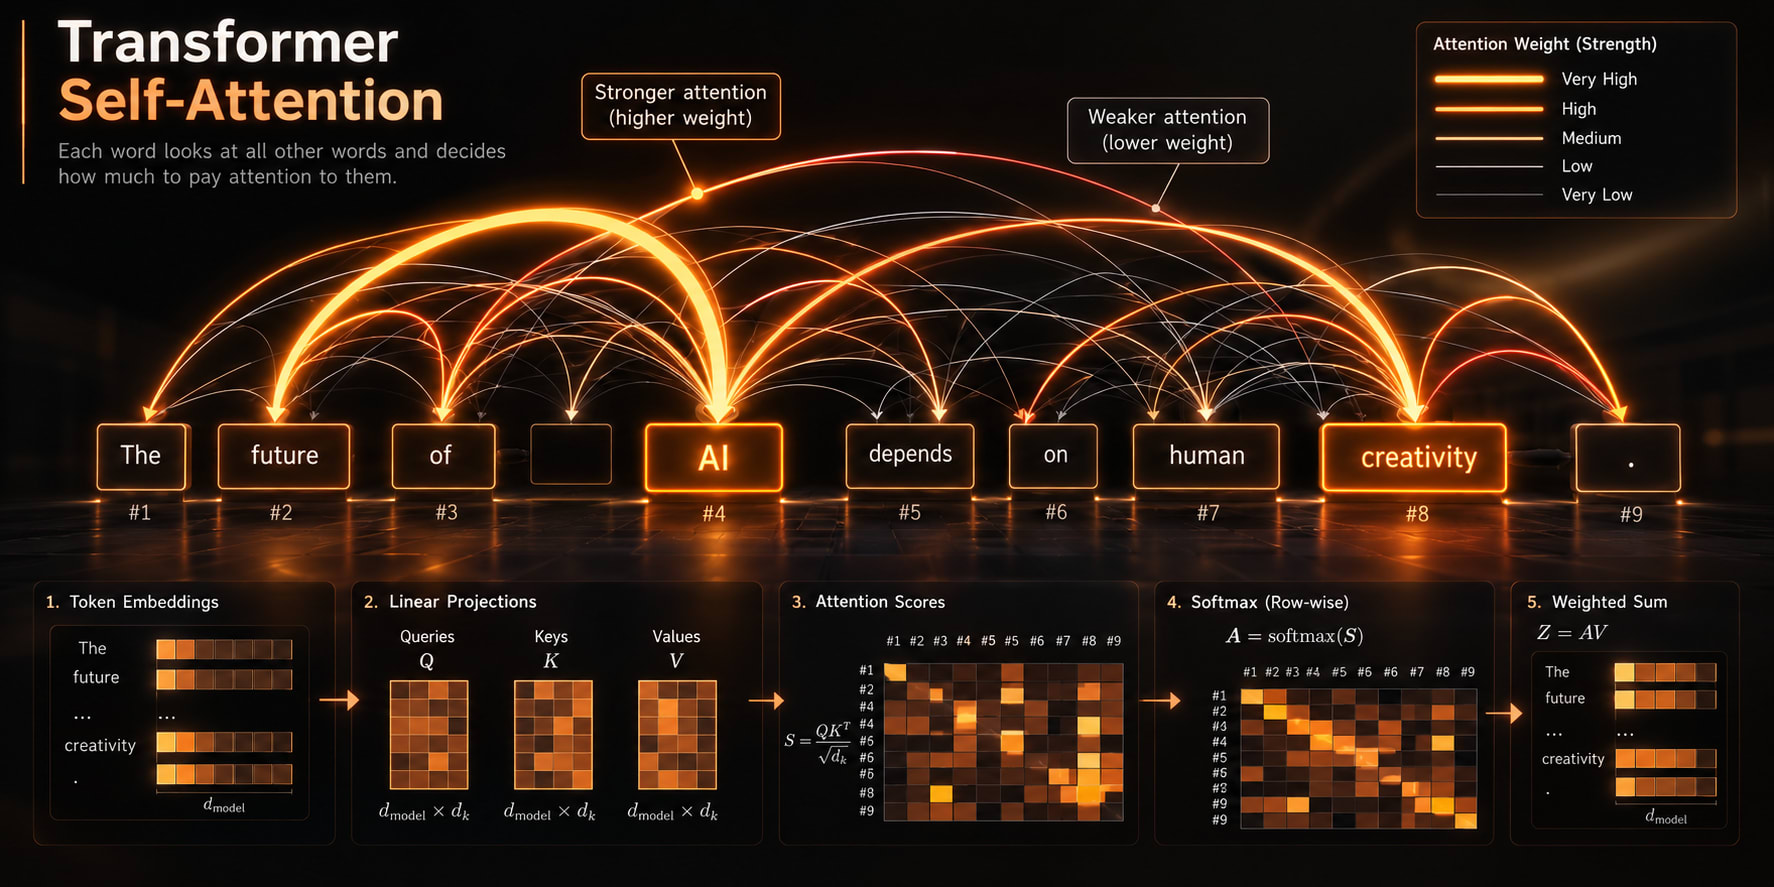
The paper introduced the Transformer, an architecture built around attention mechanisms rather than recurrence as its central sequence-processing mechanism.
Think about a sentence.
Instead of reading it like this:
word → word → word → word → word
the model can calculate relationships between tokens using self-attention.
That means a token can directly interact with information elsewhere in the sequence.
This is one of the reasons Transformers scale so effectively during training: unlike recurrent models, they can process many positions in parallel during training.
This was revolutionary.
But don't misunderstand the breakthrough.
Transformers did not magically make AI "remember everything."
They didn't eliminate every long-context problem.
What they did was provide a much more scalable mechanism for modeling relationships across a sequence.
And then researchers discovered something extraordinary:
Scaling these models could unlock surprisingly broad capabilities.
ERA 09 — MAKE THE LANGUAGE MODEL HUGE
2018–2021 · The LLM Era
Now imagine taking the Transformer...
and making it really, really large.
Train it on enormous amounts of text.
Give it huge computational resources.
Ask it to repeatedly predict what comes next.
For example:
"The capital of France is..."
The model learns that Paris is a highly probable continuation.
Do this over enormous quantities of data.
Again.
And again.
And again.
The result is a Large Language Model.
A modern LLM is generally a very large neural language model; many influential LLMs are Transformer-based.
The GPT family demonstrated this progression clearly.
GPT-2 showed that scaling a Transformer language model could produce surprisingly broad language capabilities.
Then GPT-3 demonstrated further gains from scale and showed strong few-shot performance.
And now something had changed.
The machine wasn't only choosing between:
CAT
or
DOG
It could generate an entire paragraph.
Then an essay.
Then code.
Then an explanation.
Then a story.
And that naturally leads to the next era.
ERA 10 — AI STOPS ONLY PREDICTING AND STARTS CREATING
2021–2022 · Generative AI
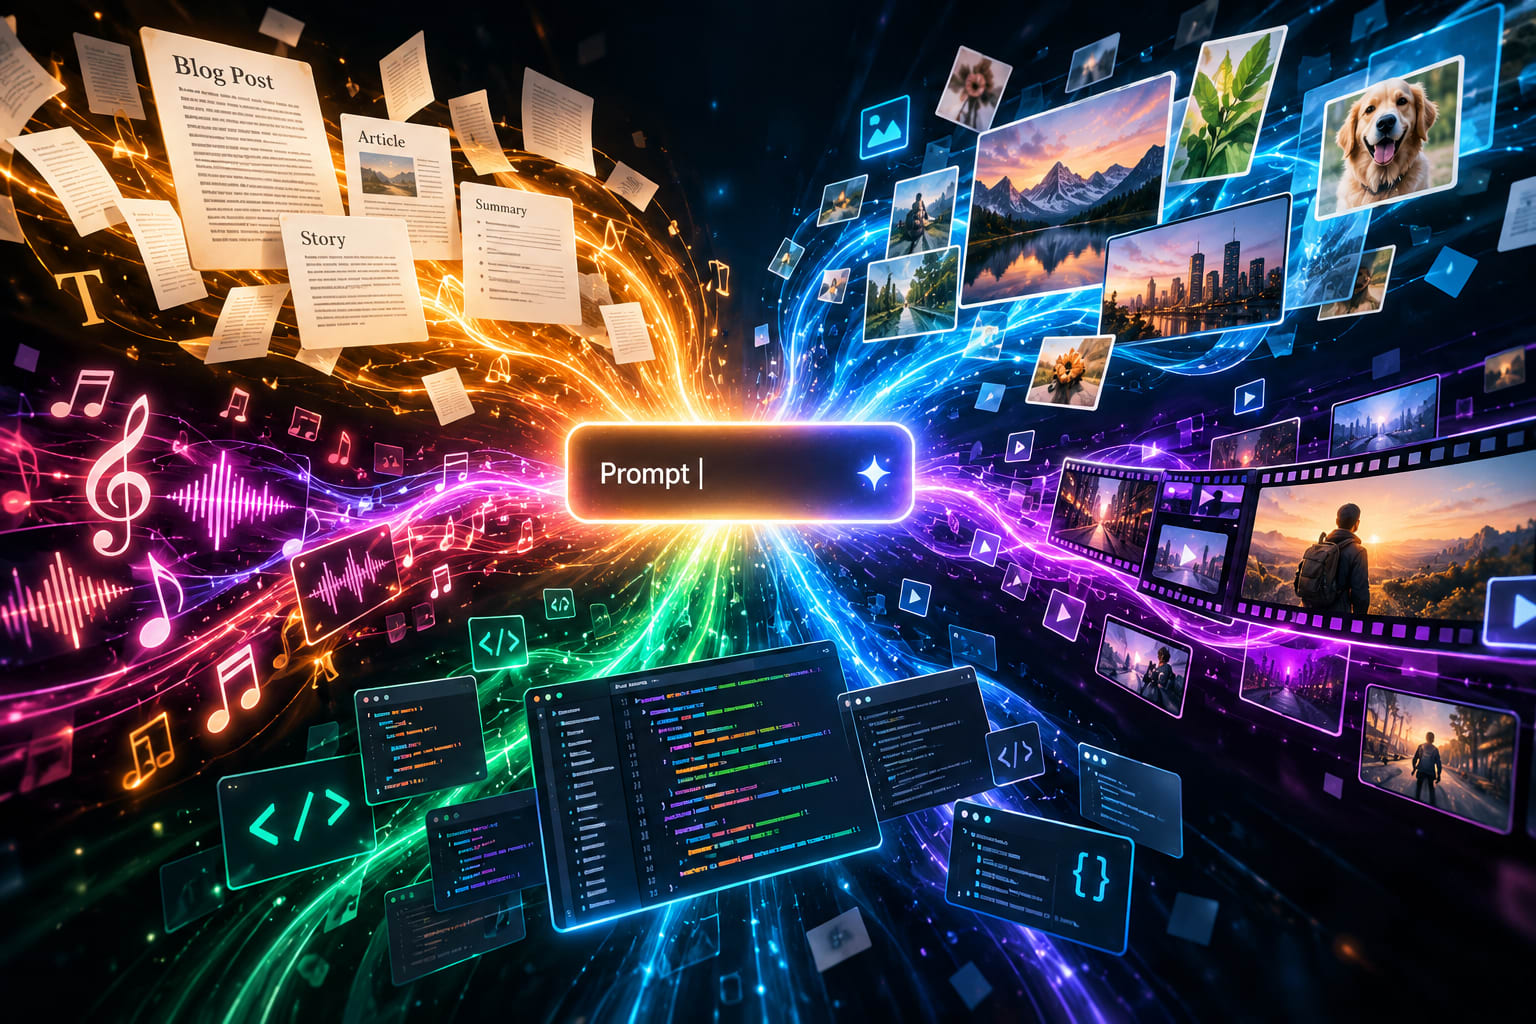
For decades, much of machine learning was built around tasks like:
classification
prediction
recommendation
detection
Now AI was increasingly being used to generate.
Give it a prompt.
Get something new.
PROMPT
  ↓
GENERATIVE MODEL
  ↓
NEW OUTPUT
Text.
Images.
Audio.
Video.
Code.
And increasingly, combinations of these modalities.
This becomes the world of Generative AI and eventually multimodal AI.
But there is an important detail:
Generated by AI does not automatically mean copyright-free.
Copyright depends on the legal circumstances and the role of human authorship. The U.S. Copyright Office has specifically discussed situations where human contribution can affect whether AI-assisted material qualifies for protection.
So AI could create.
But could ordinary people actually interact with it naturally?
That brings us to the moment that changed public awareness of AI.
ERA 11 — THE CHATGPT MOMENT
November 30, 2022 · AI Becomes Conversational
November 30, 2022.
OpenAI releases ChatGPT as a research preview.
And suddenly, millions of people discover something that feels completely different.
You don't have to learn a programming language.
You don't have to understand machine learning.
You don't even have to know how the system works.
You can simply type:
"Explain gravity like I'm five."
And it answers.
Then:
"Now explain it like I'm a physics student."
It adapts.
Then:
"Give me an example."
It continues.
Then:
"Now turn that into code."
It generates code.
The interaction feels conversational.
OpenAI described ChatGPT as a conversational model trained using Reinforcement Learning from Human Feedback (RLHF) techniques related to those used for InstructGPT.
This distinction is important too:
ChatGPT's original launch used conversation context.
The persistent Memory feature people know today came later.
So we should not look backward and say the original 2022 ChatGPT already had today's memory system.
But even without that later feature, something enormous had happened.
AI had become something ordinary people could simply talk to.
ERA 12 — FROM AI MODEL TO AI ASSISTANT
2022–Today · The Modern AI Era
For decades, AI was mostly experienced indirectly.
A recommendation system suggested a movie.
A computer vision system recognized a face.
A machine-learning model predicted fraud.
A translation system converted one language into another.
But now one interface could bring many capabilities together.
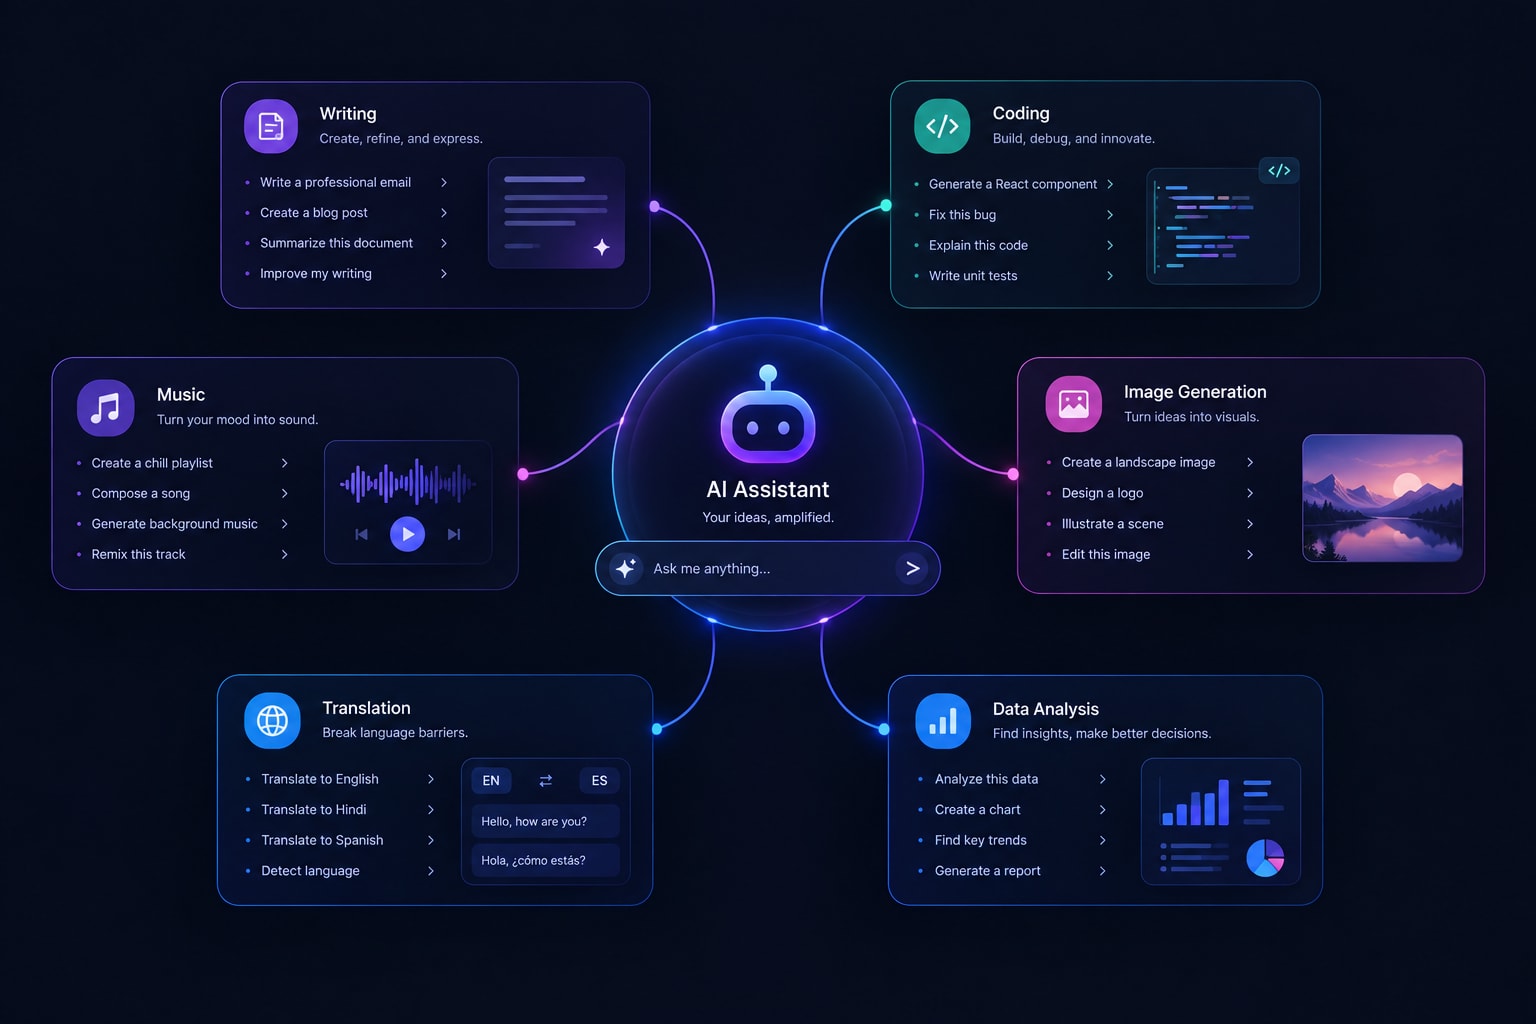
A person could ask an AI system to:
write
summarize
translate
generate code
explain
analyze information
brainstorm
work with documents
help debug software
generate presentations
and perform many other knowledge-work tasks.
And increasingly, these systems became multimodal.
They could work with combinations of:
text
images
audio
video
documents
The important shift was no longer only:
"Can AI perform one task?"
It became:
"How many different kinds of work can one AI system help a human perform?"
And that is where we are today.
THE ENTIRE AI STORY IN ONE VIEW
Think of AI history as a sequence of questions.
ERA 01 — CAN MACHINES THINK?
1950–1956
Turing → Imitation Game → McCarthy → AI gets its name
↓
ERA 02 — CAN WE PROGRAM INTELLIGENCE?
1950s–1980s
Rules → logic → symbolic AI → expert systems
↓
ERA 03 — WHY IS AI NOT LIVING UP TO THE PROMISE?
1970s–1980s
AI winters → funding declines → expectations reset
↓
ERA 04 — CAN MACHINES LEARN FROM EXAMPLES?
1950s–2000s
Machine learning → statistical methods → learning from data
↓
ERA 05 — CAN MACHINES LEARN THE FEATURES TOO?
1980s–2010s
Neural networks → backpropagation → deep learning
↓
ERA 06 — CAN MACHINES SEE?
2012
ImageNet → AlexNet → computer vision breakthrough
↓
ERA 07 — CAN MACHINES UNDERSTAND LANGUAGE?
2010s
RNNs → LSTMs → neural NLP
↓
ERA 08 — WHAT IF EVERYTHING COULD ATTEND TO EVERYTHING?
2017
Transformer → self-attention → scalable sequence modeling
↓
ERA 09 — WHAT HAPPENS IF WE MAKE THE MODEL HUGE?
2018–2021
GPT → GPT-2 → GPT-3 → Large Language Models
↓
ERA 10 — CAN AI CREATE?
2021–2022
Generative AI → text → images → audio → video → multimodal systems
↓
ERA 11 — CAN HUMANS JUST TALK TO AI?
November 30, 2022
ChatGPT → conversational AI → AI enters mainstream public use
↓
ERA 12 — WHAT CAN HUMANS AND AI DO TOGETHER?
2022–Today
AI assistants → coding → analysis → content creation → multimodal interaction → increasingly capable AI systems
AND HERE IS THE REAL STORY
The history of AI isn't really the story of one invention.
It is the story of changing questions.
First:
"Can machines think?"
Then:
"Can we describe intelligence with rules?"
Then:
"Can machines learn from examples?"
Then:
"Can machines learn the features themselves?"
Then:
"Can machines see?"
Then:
"Can machines understand language?"
Then:
"Can machines connect distant pieces of information?"
Then:
"Can we make language models enormous?"
Then:
"Can AI create?"
And finally:
"Can humans simply talk to a machine and work together?"
That is the journey.
From rules...
to learning...
to deep learning...
to attention...
to language models...
to generative AI...
to AI assistants.
And the fascinating thing is this:
Every time humanity thought it had figured AI out...
we discovered a new limitation.
And then someone asked a new question.
That question started the next era.